SIGReg and repulsion in JEPA training
A September 28, 2026 post describes how SIGReg, used by LeJEPA and LeWM, approximates a sliced MMD whose expansion reveals repulsion between pairs of samples in a batch.
Read articleKnowledge you can apply
Daily bookmarks: relevant news, facts and discoveries.
A September 28, 2026 post describes how SIGReg, used by LeJEPA and LeWM, approximates a sliced MMD whose expansion reveals repulsion between pairs of samples in a batch.
Read articlePublished on September 27, 2026, HySparse2 is described as a hybrid sparse-attention method with two-level KV sharing, aimed at efficient prefill and compact KV-cache storage for agents with long contexts and multiple interactions.
Read articleAn ICLR 2026 paper addresses efficient autoregressive inference for probabilistic Transformer models and, according to the post, a decoding bottleneck.
Read articlePublished on September 27, 2026, the item describes LENS, a reinforcement-learning framework that jointly optimizes reasoning and text-guided image segmentation.
Read articleA September 27, 2026 publication reports preliminary ablations suggesting V=K+M is an effective architectural choice; the result still needs validation at larger scales.
Read articleA report claims that FairPlay-protected iOS IPAs can be decrypted without a physical iPhone or jailbreak. The claim may interest people studying app protection, but the briefing does not verify it.
Read articleA paper on intra-kernel GPU tracing through binary-level instruction splicing; its preview describes probes inserted into kernels to record execution data.
Read articleAn article presents NSA, a trainable sparse-attention mechanism that combines algorithmic choices with hardware-aligned optimizations for efficient long-context modeling.
Read article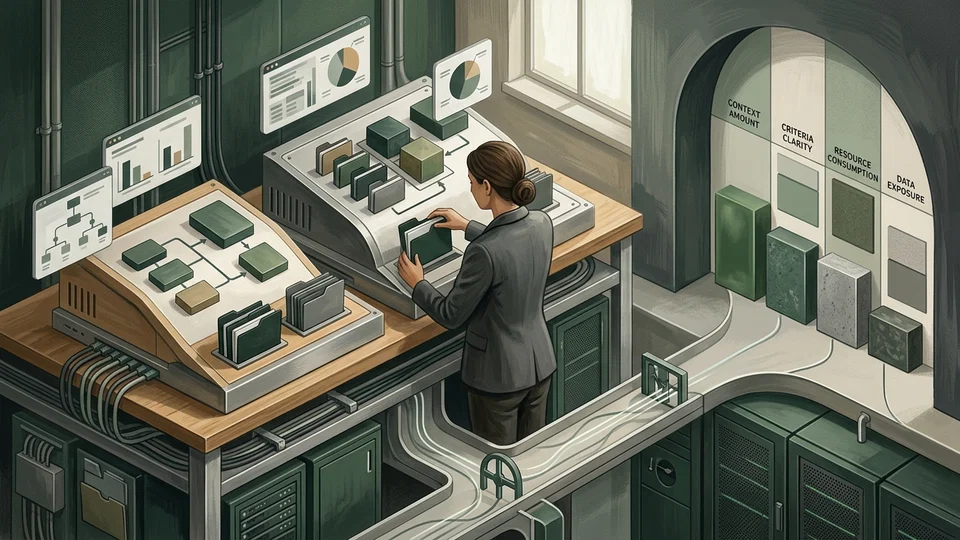
A more elaborate workflow does not always improve outcomes. Compare components by task quality, consumption and data exposure.
Read articlePublished on September 26, 2026, the article compares standard Transformers and Mixture-of-Experts, with and without looping. The authors report that Looped-MoE scales better than the standard baseline, while dense-looping models do not.
Read articleAn article published on September 26, 2026 follows a vLLM request from queue to decoding and explains per-iteration scheduling and KV-cache block allocation.
Read article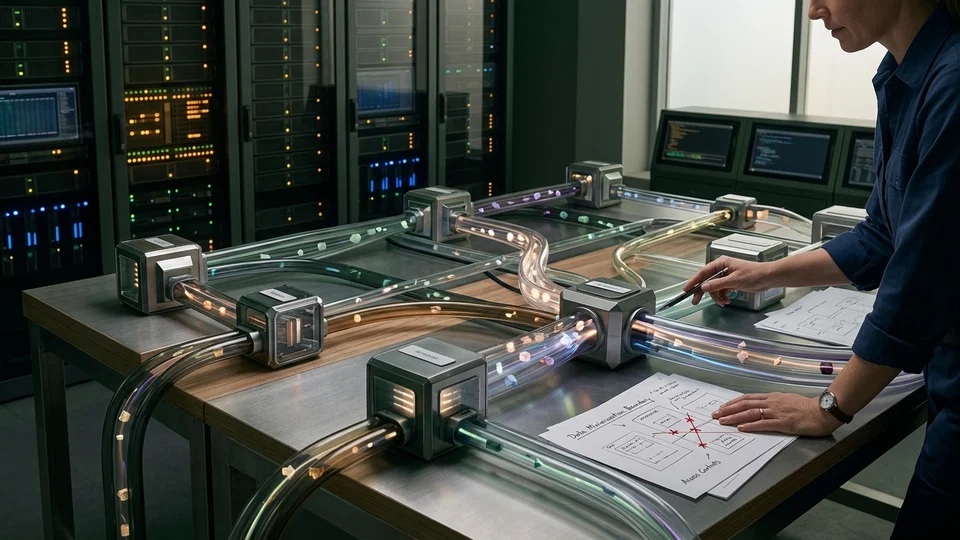
Internal representations do not make information anonymous. Define data boundaries before connecting multiple models.
Read articlePublished on September 26, 2026, Unsloth's guide ranges from beginner to advanced and covers using GRPO to train reasoning models.
Read articlePublished on September 26, 2026, the note presents JAZ, a framework using a single recursive code primitive for agent loops, and reports a claim of lower cost and better performance than two alternatives.
Read articleFewer components can ease maintenance. Data and action boundaries must remain explicit at every step.
Read articlePublished on September 26, 2026, the work presents a theoretical criterion for feature-map spikiness and a channel-wise polarity-aware feature map. The authors evaluate the approach across six families of visual tasks.
Read articleA study uses program-generated byte sequences and an adaptive generator to investigate whether systems can learn transferable structures without training on natural data.
Read articlePublished on September 26, 2026, the paper presents an LLM compression method using singular value decomposition (SVD) that updates compressed weights after truncation.
Read articleAn article reports three kinds of computational redundancy across loops in looped Transformers. The authors say exploiting them reduces latency by 1.65× and memory use by 6×.
Read articlePublished on September 26, 2026, the bookmark says Transformer-Within-Transformer replaces contiguous groups of similar layers with substitute attention layers. In DINOv2, it reports about half the compute, with a small drop in accuracy.
Read articleRota Nacional
30 days, no card, with a starting quota. After that, Pix credit from R$ 10,00.